German deep-tech startup Daisytuner has raised €6 million in seed funding to tackle one of the biggest infrastructure challenges in artificial intelligence: making AI software run efficiently across different types of processors. Co-led by Elaia and LEA Ventures, the round will support the company’s AI compiler technology and expansion of its newly launched Daisyflow inference engine. Rather than asking businesses to rewrite applications whenever they choose different hardware, Daisytuner wants software to adapt to the processor underneath it.
A €6M Seed Round Backs a New Approach to AI Computing Infrastructure
Daisytuner announced its €6 million seed funding round on November 16, 2026. The investment was co-led by European venture capital firms Elaia and LEA Ventures, with participation from Amadeus APEX Technology Fund and Seedcamp. Based in Darmstadt, Germany, the company plans to use the capital to expand its engineering team, advance its compiler technology and bring Daisyflow to more enterprise customers. The funding arrives as AI infrastructure providers search for ways to reduce the cost and complexity of running increasingly demanding models. The challenge is no longer simply finding powerful processors. Companies also need software that can use different processors efficiently without requiring extensive manual engineering. Daisytuner is positioning its technology around that problem. The company has not disclosed a valuation alongside the seed announcement, and the €6 million represents the new round rather than a stated lifetime funding total.
The AI Industry Has a Hardware Problem Beyond Nvidia’s Dominance
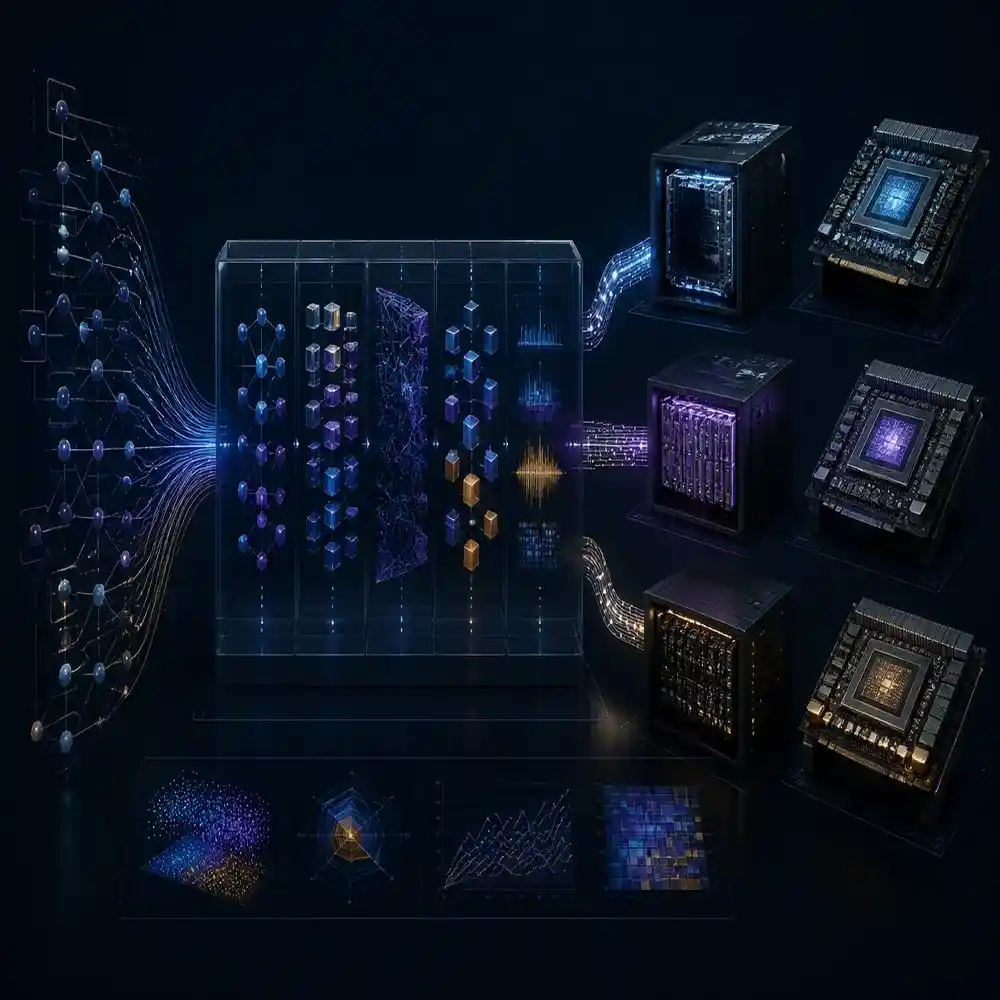
Nvidia has become central to modern AI computing because its GPUs and CUDA software ecosystem are widely used to train and operate AI models. However, the growth of artificial intelligence is creating demand for computing capacity that extends beyond one hardware supplier. AMD is expanding its accelerator business, while companies such as Tenstorrent and other emerging chip developers are building alternative processors for specialised workloads. The problem is that software developed for one hardware ecosystem may not automatically deliver the same performance on another. Developers often need to adapt code, optimise operations and test different configurations before a new processor becomes commercially useful. This creates an additional engineering burden for enterprises and hardware manufacturers. Daisytuner wants to make that transition easier by allowing applications to be compiled and optimised for different chip architectures. Its ambition is not to eliminate Nvidia from the market, but to reduce the software barriers that keep businesses tied to a particular computing platform.
DOCC Compiler Turns Application Code Into Hardware-Specific Instructions
At the centre of Daisytuner’s technology is DOCC, an open-source compiler designed to translate software into code that can run efficiently on different processor architectures. It supports programming inputs including PyTorch, NumPy, C and C++, converting them into an intermediate dataflow representation before generating native code for supported hardware platforms. In simple terms, the compiler acts as a translator between an application and the processor it needs to use. Instead of manually rebuilding an application for every chip, developers can use the compiler to handle much of the technical adaptation. The system supports established environments such as Nvidia CUDA and AMD ROCm, while the company is also working towards newer accelerator architectures. This is important because different chips have different ways of processing information, managing memory and executing parallel calculations. A compiler that understands those differences could help developers use more of the hardware capacity already available to them.
AI Agents Automatically Search for Better Ways to Run Code
Daisytuner combines its compiler with AI agents that continuously test possible software optimisations on real hardware. These agents can investigate different ways of executing an operation, benchmark the results and identify configurations that improve performance. Importantly, the compiler checks whether an optimisation remains correct before accepting it. Successful techniques are then stored in a performance database, allowing the platform to reuse proven solutions when it encounters similar workloads in the future. This creates a learning process in which earlier optimisation work can help improve later compilation tasks. The approach matters because manual performance engineering is expensive and highly specialised. Engineers traditionally spend significant time adjusting software for each new processor or model architecture. Automating more of this process could reduce the time required to bring new chips into production and make advanced optimisation techniques accessible to a wider range of companies.
Daisyflow Brings the Compiler Technology Into Enterprise AI Inference
Alongside its funding announcement, Daisytuner launched Daisyflow, an AI inference engine built on top of its compiler and optimisation platform. Inference is the stage where a trained AI model processes requests and generates outputs, such as answering a question, analysing an image or producing a recommendation. Daisyflow is designed to serve language, vision, speech and recommendation models within a customer’s own infrastructure. It includes capabilities such as model routing, batching and standard application interfaces, including OpenAI-compatible APIs for language models. This gives businesses a way to deploy AI applications without depending entirely on an external model-serving cloud. The product is intended for enterprises, cloud providers and hardware companies that want to operate workloads across different processors while retaining control over their data and infrastructure. Daisytuner’s offering therefore extends beyond code compilation into the operational software required to run AI models in production.
An Early AMD Benchmark Offers Evidence of the Multi-Chip Strategy
One of Daisytuner’s first reported performance results provides a concrete example of its approach. The company says that Qwen 2.5, an open-weight AI model, ran up to 18% faster than the widely used vLLM inference system on AMD Instinct GPUs when using its optimised setup. The result is relevant because it shows how compiler and execution-level optimisation can improve performance on hardware outside Nvidia’s CUDA ecosystem. However, the figure is an early company-reported result for a particular model, inference setup and hardware platform. It should not be interpreted as an across-the-board performance advantage over vLLM or proof that every model will run faster on every alternative processor. Daisytuner has also been working with chip companies including Tenstorrent and Q.ANT, according to its founder, giving it exposure to different computing architectures. The real test will be whether these early results translate into consistent advantages across a broader range of workloads and customer environments.
Founders Are Building a European Software Layer for the Global Chip Market
Daisytuner was founded in Germany in 2024 by Lukas Trümper and Adrian Schmitz. Trümper previously worked on performance engineering and GPU computing, while the founding team brings research and engineering experience connected to institutions including ETH Zurich, the Technical University of Munich, RWTH Aachen University and TU Darmstadt. The company has also drawn on research experience associated with Lawrence Livermore National Laboratory. According to Tech Funding News, Daisytuner’s team has grown to 12 people and is targeting more than 20 employees by early 2027. The startup is working with chipmakers and engaging with cloud providers and enterprise customers, while its founder has said that early commercial discussions are progressing. Its approach is particularly relevant to European AI infrastructure ambitions: rather than attempting to build a competing GPU from scratch, a software company can help make a wider range of processors commercially useful. That creates a potential role for European engineering expertise within the global AI hardware ecosystem.
Daisytuner’s Opportunity Depends on Making Hardware Independence Work at Scale
The long-term opportunity for Daisytuner is tied to the growing need for more flexible AI infrastructure. As new chips enter the market, enterprises will want the freedom to select processors based on performance, price, availability, energy consumption and data requirements. But supporting several hardware platforms is technically difficult, and a compiler that works well for one model or accelerator may need further optimisation for another. Daisytuner must therefore prove that its technology can deliver reliable results across a broad range of models, processors and production environments. It also faces competition from companies developing their own compiler and inference systems. Its advantage will depend on the quality of its optimisation database, the effectiveness of its automated agents and the ability to turn early benchmarks into dependable enterprise deployments. The €6 million seed round gives the company resources to pursue that challenge. Its larger ambition is to make AI software less dependent on a single hardware ecosystem and help businesses get more performance from the computing infrastructure they can access.