AI agents are becoming easier to build, but making them reliable enough to handle real customers, sensitive information and critical business operations remains a major challenge. An agent might perform perfectly during a demonstration and still fail when a customer asks an unexpected question, changes an instruction or requests an action that violates company policy. Israeli-founded AI infrastructure startup Plurai wants to solve this problem by applying the simulation techniques used in autonomous driving to enterprise AI agents. The company has raised $13 million in seed funding led by Team8, with participation from U&I, Velocity and Mercer, alongside more than 20 angel investors and technology leaders. Its platform creates simulated environments in which AI agents are exposed to thousands of realistic and difficult situations, helping engineering teams discover weaknesses before those systems reach customers. Plurai’s larger ambition is to make continuous testing and improvement a standard part of deploying autonomous AI software.
Why AI agents fail even after passing internal tests
Most businesses test AI agents using predefined questions and tasks before releasing them. However, real users rarely behave in predictable ways. A customer support agent might answer ordinary questions correctly but give incorrect information after a long conversation. A purchasing agent might follow instructions until a user asks it to ignore a spending limit. An enterprise research agent might find information in one database but produce an incorrect answer when it needs to combine several sources. These failures are difficult to identify through conventional testing because the number of possible conversations, tools and situations is enormous. Once an agent enters production, manually reviewing every interaction becomes expensive and time-consuming. Plurai believes companies need a system that actively searches for these unusual situations instead of waiting for customers to discover them.
Plurai builds a digital twin of each AI agent and its working environment
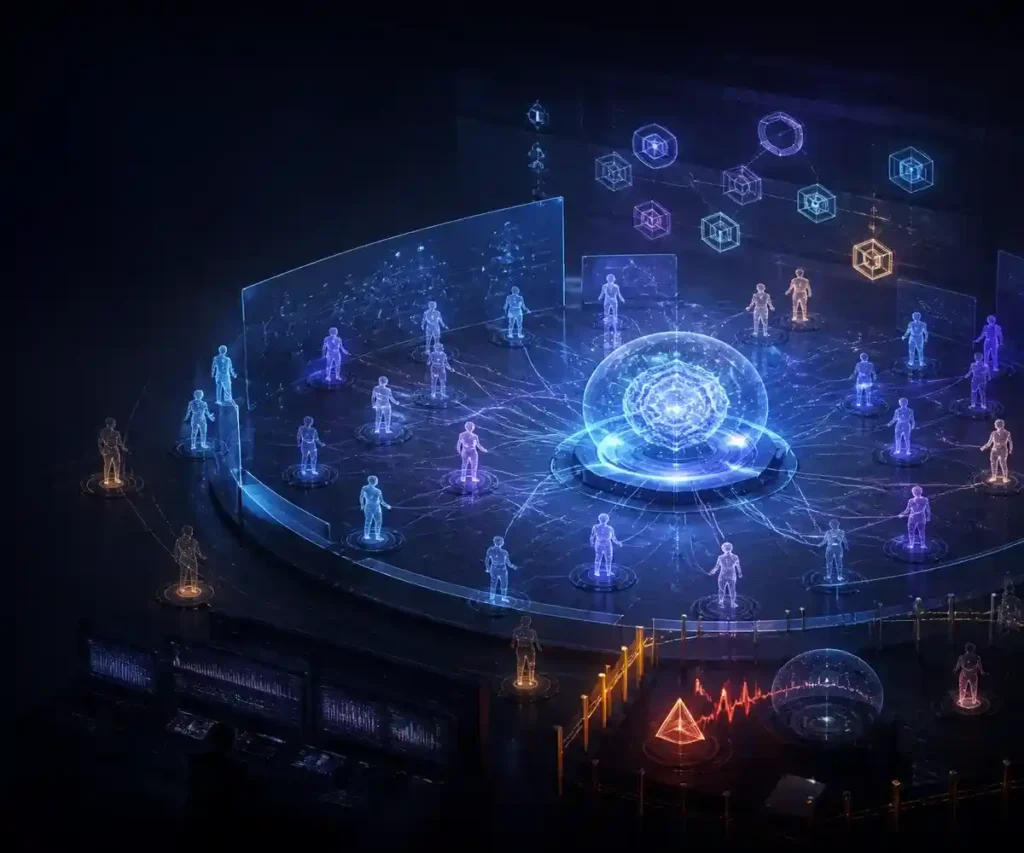
The platform starts by creating a digital representation of an AI agent and the environment in which it operates. This includes the company’s knowledge base, connected tools, software systems and internal policies. Plurai then places the agent inside a simulated environment populated by realistic and adversarial users who generate thousands of different requests and situations. These simulations are designed to expose problems such as hallucinations, unauthorised actions, broken tool calls, failed tasks, policy violations and sensitive data leaks. For example, a simulated customer might repeatedly pressure an agent to reveal restricted account information, while another might attempt to persuade it to ignore an approval requirement. By reproducing these interactions in a controlled sandbox, developers can discover weaknesses without exposing real customers or company systems to the same risks. The company is making this approach available through its Plurai Simulation product, including integrations with developer tools such as Claude Code, OpenAI Codex and GitHub Copilot.
Finding a failure is only the first step: the system also helps fix it
Plurai’s approach goes beyond traditional AI evaluation and observability tools. When a simulation identifies a failure, the platform is designed to explain why the agent behaved incorrectly and generate proposed fixes for developers to review and integrate into their own code. The same scenario can then be replayed to check whether the problem has been resolved. Developers can also test related situations to determine whether a change has introduced new weaknesses elsewhere. This creates a repeatable development process in which every discovered failure becomes another test case. Instead of manually debugging isolated customer complaints, engineering teams can build an expanding collection of scenarios that challenge their agents before and after deployment. The objective is to make AI testing more continuous and systematic, rather than treating evaluation as a one-time activity before launch.
Smaller AI models could make continuous agent monitoring affordable
One of Plurai’s most important technical ideas is using simulation data to train specialised small language models, or SLMs, for individual AI agents. Large frontier models can be expensive to run continuously, particularly when every agent action must be checked against company policies and operational requirements. Plurai uses the results of its simulations to create smaller models tailored to specific tasks. These models can potentially perform selected agent functions while also evaluating behaviour, checking actions and enforcing business rules during production. The company says they allow organisations to monitor every interaction rather than relying on limited samples or repeatedly using expensive frontier models. This is also where Plurai’s relationship with NVIDIA and Nebius becomes relevant. In joint work for a global enterprise customer, Plurai says its post-trained models outperformed OpenAI and Anthropic frontier models on accuracy at approximately 40 and 44 times lower cost, respectively. These are company-reported comparative results from a specific project, not a general guarantee that smaller models will outperform frontier systems across all workloads.
Experience in autonomous driving shaped the founders’ approach
Plurai was founded by Dr. Ilan Kadar and Dr. Elad Levi, who previously worked together at autonomous-driving technology company Nexar. Their earlier work involved developing reliable AI systems for high-stakes environments, including work connected to Waymo’s autonomous driving technology. That experience influenced how they approached the agent reliability problem. Self-driving systems cannot be tested only under normal road conditions because rare events, unusual weather and unexpected human behaviour can create dangerous situations. Simulation allows developers to reproduce those conditions repeatedly before deploying vehicles on public roads. Kadar and Levi believe the same logic should apply to autonomous software agents. Their research background also includes BARRED, a method for generating synthetic training data for specialised small models that was accepted at ICML 2026, as well as research into serving hundreds of tailored models on a single GPU. This combination of simulation, synthetic data and efficient model serving forms the technical foundation of Plurai’s strategy.
Team8 leads the investment as AI reliability becomes an infrastructure market
The $13 million seed round was led by Team8, with U&I, Velocity and Mercer participating. More than 20 angel investors and industry leaders also backed the company, including CyberArk founder Udi Mokady and Reah Miyara, Senior Director of Google Models at Google Cloud and a former OpenAI model evaluation lead. Dr. Eyal Carmi, CTO of Microsoft 365 Copilot, has joined Plurai’s advisory board. The company is already working with enterprises across AI-native and highly regulated industries, including major financial institutions and Fortune 500 businesses, although it has not publicly named all of its design partners. Its platform has also become generally available to developers through a free starting tier. That distribution strategy matters because Plurai wants developers to integrate simulation into their existing workflows instead of introducing an entirely separate testing process after an agent has been built.
Plurai is betting that simulation will become essential to the AI agent stack
The wider opportunity for Plurai comes from a shift in enterprise software: businesses are beginning to deploy agents that perform tasks rather than simply generate answers. As those systems gain access to databases, customer records, payment tools and internal applications, the consequences of incorrect actions become more significant. Testing, simulation and continuous monitoring could therefore become essential infrastructure for companies deploying autonomous AI at scale. However, Plurai must still prove that its simulated environments accurately represent real business behaviour, that its proposed fixes do not introduce new failures and that its smaller models maintain reliability across changing data and workflows. Simulation cannot guarantee that every real-world situation will be anticipated, and human oversight will remain important for high-impact decisions. Its $13 million funding gives the company capital to expand its research and enterprise adoption. If it succeeds, Plurai could establish an important category between AI development and production deployment: the reliability infrastructure that helps agents become safer, more accurate and less expensive to operate.
Sources and further reading
- Plurai – Official $13M Seed Announcement and Product Launch
- Plurai – AI Agent Simulation and Post-Training Platform
- Team8 – Why We Invested in Plurai
- TechCrunch – How Plurai Applies Autonomous Driving Simulation to AI Agents
- Plurai – Funding, NVIDIA Partnership and Reported Customer Results
- Plurai – Simulation, Post-Training and Developer Access